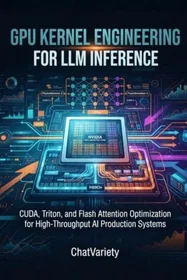
GPU Kernel Engineering for LLM Inference: CUDA, Triton, and Flash Attention Optimization for High-Throughput AI Production Systems
Compare prices and shops

GPU Kernel Engineering for LLM Inference: CUDA, Triton, and Flash Attention Optimization for High-Throughput AI Production Systems
€8.73
In stock
We have found the product in 1 shop, 1 of which are PriceSpy paying partners and have a direct link to the shop. How we display prices and shops.
Insights
Product information
The best price for GPU Kernel Engineering for LLM Inference: CUDA, Triton, and Flash Attention Optimization for High-Throughput AI Production Systems right now is €8.73. PriceSpy compares deals and offers from online and local shops.
Basic information
Product name
GPU Kernel Engineering for LLM Inference: CUDA, Triton, and Flash Attention Optimization for High-Throughput AI Production Systems
Price History
The graph shows the lowest price over time for the variant (such as color or size) that has been the cheapest at each point in time. Shipping and used products are not included. Read more about price history.